 ChatGPT
 Perplexity

Legacy system modernization can keep revenue flowing when each phase has a cutover and recovery plan that works. Here's how to choose an approach for each system and move it in phases.
Highlights:
- Pick a modernization approach for each system, from retire to rebuild.
- Rebuild only when the core can't support features the business needs.
- Parallel running and a tested rollback reduce the risk of disruption at cutover.
The first version of your product got you to product-market fit, and now it limits how fast you can grow. Releases slow down because nobody wants to touch the core, integrations run on workarounds and every dependency update feels like a bet on production.
We've dealt with this on live products. We moved a 40TB music library for one DJ platform from a single physical server to AWS with zero downtime. We've also rebuilt existing products and planned how their users, subscriptions and tracking data would move to the new versions.
This legacy system modernization guide draws on that work to help founders answer one question: Is rebuilding necessary, or can we fix what we have?
If you'd like a second opinion on your own stack, our tech leads can review it with you and outline a first phase that fits your release schedule.
What legacy system modernization covers (and what it doesn't)
Legacy system modernization means changing a system that still runs core operations so it meets current business needs at an acceptable cost and risk. The change can touch the code, architecture, infrastructure or data, and its scope can be anything from new hosting to a full rebuild.
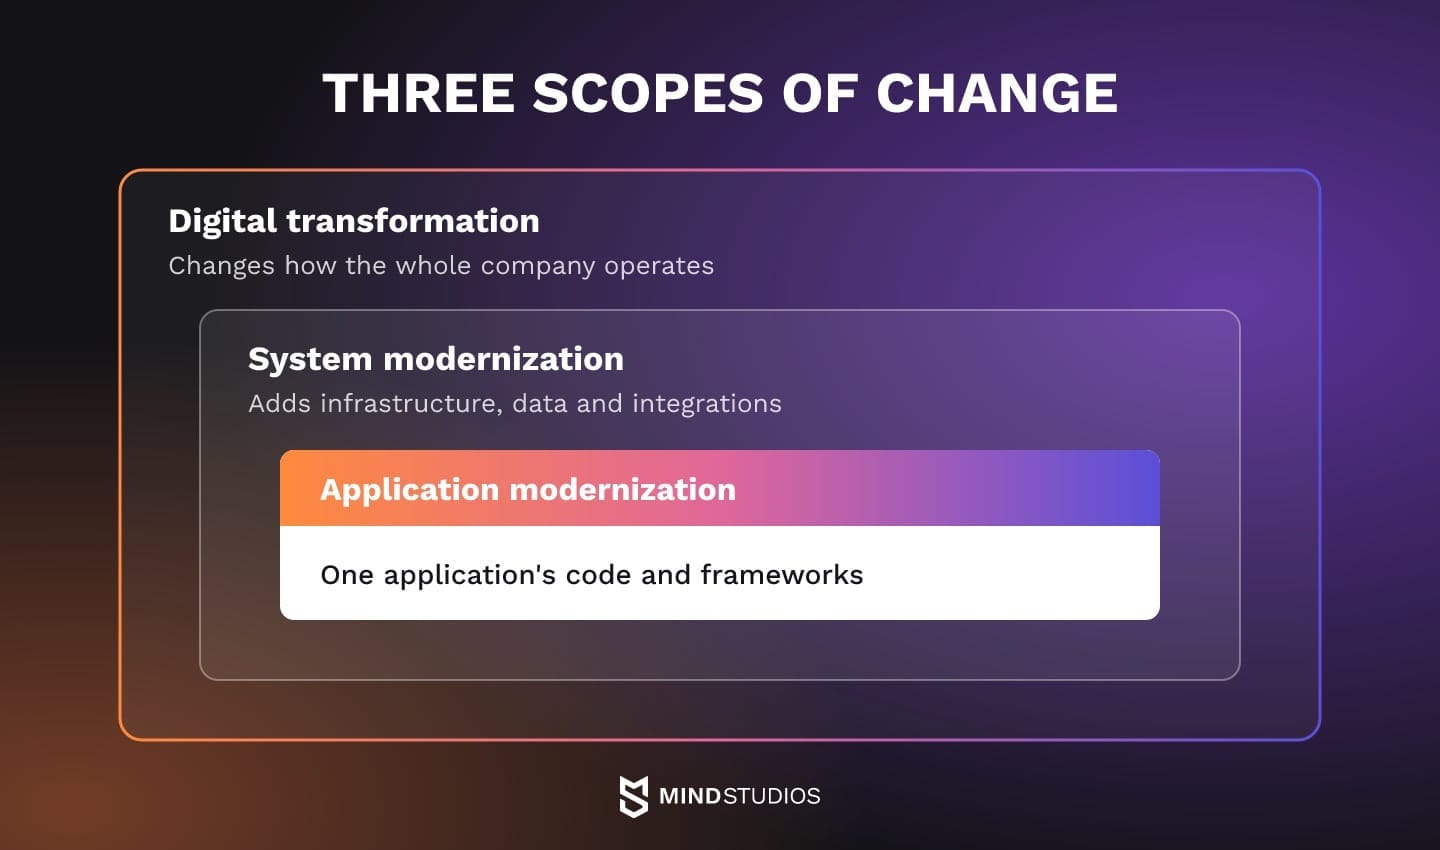
A new interface on the same core doesn't count, because the bottlenecks stay. A move to new hosting does count when it removes a real constraint, such as failing hardware, capacity limits or support costs. Digital transformation changes how the whole company operates, and modernization fixes the systems that change depends on.
A system becomes legacy when it starts to constrain the business, whatever its age. In a growing company, that typically means:
- a shared codebase and deploy that slow every release
- on-premise hardware that can't keep up with demand
- a framework, OS or language version that no longer gets updates
Mainframe and COBOL estates need their own specialists, so this guide focuses on web platforms, mobile backends, internal tools and the data pipelines between them.
Legacy system vs legacy application modernization
Legacy application modernization changes one application: its code, architecture, frameworks and dependencies. Legacy system modernization also covers the infrastructure, data stores, integrations and processes around it.
In practice the two overlap: a framework upgrade can require new hosting, which then reveals code that won't run there unchanged. That's why both layers need scoping before you estimate either one.
Signs a legacy system costs more than it saves
A system is due for modernization when keeping it running takes the budget and attention that growth needs. Typical signs: a stack that can't be updated, integrations held together by workarounds, rising maintenance spend, data other systems can't reach, and security exposure that grows every month without patches.
In GAO's 2025 report, US federal agencies said they typically spend about 80% of more than $100 billion a year on operating and maintaining existing IT, legacy systems included. GAO also found that seven of the 11 most critical legacy systems it reviewed run with known cybersecurity vulnerabilities.
For your company, the useful measure is last quarter's split of engineering hours between upkeep and new work.
IBM's 2026 breach report puts the global average cost of a data breach at $4.99 million, a record high and 12% more than the year before. IBM doesn't break it down by system age, but an unpatched critical component belongs in your assessment as a business risk.
On the DJ platform mentioned above, a frozen stack looked like this: the Ubuntu version on the single server was too old to accept dependency updates, including Node.js, and updating the OS risked taking the platform down. Development stayed frozen until the migration.
Run each system through these questions, then rank them by business impact, because one critical failure risk can outweigh several integration problems:
- Is any part of the stack (framework, OS, database) impossible to update without risking production?
- Does connecting a new tool (CRM, analytics, payments) need workarounds or manual exports?
- Does more engineering time go to keeping the system running than to new features?
- Is critical data stored where reports and other systems can't reach it?
- Are any components past vendor support and security patches?
- Does only one person (or nobody still on the team) understand how the core works?
Legacy modernization strategies: the 7 Rs compared
A common reference set is the 7 Rs from AWS Prescriptive Guidance: retire, retain, rehost, relocate, repurchase, replatform and refactor or re-architect. Two more approaches sit outside the AWS set. Encapsulation wraps the system in an API layer, and rebuild rewrites it from scratch.
Lists labeled "7 Rs" vary by author. We use the AWS version and keep encapsulation and rebuild as separate rows so they aren't confused with repurchase.
Each R applies to one system at a time. A company with five systems may retire one, rehost two, wrap the billing engine in an API layer and rebuild the core.
| Approach (what changes) | When it fits | When it doesn't |
|---|---|---|
| Retire (shut it down) | Little use left; upkeep exceeds value | Hidden processes still depend on it |
| Retain (keep as is) | Recently upgraded or held by data residency rules | It blocks other moves or has open vulnerabilities |
| Rehost (new hosting, same code) | Hardware is the risk; code still works | The code itself blocks change |
| Relocate (whole platform moves) | Already virtualized; you need a fast move | The platform is the problem |
| Repurchase (switch to a product) | A standard process that SaaS covers | The system is what sets you apart |
| Replatform (new runtime, light changes) | Stack can't be updated; managed services help | Architecture is the bottleneck |
| Refactor or re-architect (new structure) | Monolith slows releases or can't scale | You need a quick exit from failing hardware |
| Encapsulation (API layer around it) | Core works; integrations lag | The core itself fails or can't be secured |
| Rebuild (rewrite from scratch) | Core can't support needed features | A working core only needs new hosting |
Each row carries its own risk, so name it before you commit. Rehost and relocate change the least code, but you carry today's code problems onto a new bill. If the cloud is where you're headed, our guide to moving enterprise systems covers that path in depth.
Repurchase saves you the build but adds vendor dependency, per-seat pricing and a migration into someone else's data model. Refactoring changes the structure itself, and for large migrations AWS generally recommends modernizing applications after the move instead of during it. Rebuild carries scope risk, because the new system has to reproduce years of behavior that nobody wrote down.
When the core still works, an API layer can connect new tools while the team plans deeper changes. Later, that layer becomes the point where you replace the system piece by piece, provided you set a date to come back to the core.
Retire and retain are valid outcomes too. A system nobody uses can be shut down once its remaining dependencies are rerouted and its data is archived for the required retention period. Keeping one on purpose with a review date frees budget for the systems that limit growth.
How to choose a legacy modernization strategy for each system
Score each system on business value and technical health, then pick the least disruptive approach that removes its real constraint. A valuable system in poor shape usually justifies deeper change. A low-value one in poor shape is a candidate to retire, and healthy systems may need only rehosting, an API layer or a review date.
Before scoring, agree on what the project is for: revenue, cost or risk. Growth points the assessment at the system blocking the next feature or market, cost at hosting, licenses and maintenance, and risk at security gaps and single points of failure. A system in poor health can wait when it touches none of the three.
These factors shape the score:
| Factor | What to ask | How it shapes the choice |
|---|---|---|
| Business value | Does revenue or a key process depend on it? | High value justifies deeper change if health is poor |
| Technical health | Can the team change it safely? | Poor health limits rehosting to a temporary step |
| Risk exposure | What breaks if it fails tomorrow? | High exposure moves it up the queue |
| Maintenance cost | How much budget keeps it alive? | Rising cost favors replatform or repurchase |
| Coupling | How many systems call it? | Tight coupling favors encapsulation and phases |
| Data and regulation | Where must data live, and who audits it? | Residency rules can force retain or a specific region |
Retire, retain or move
Start with these questions:
- Does anyone still need the system? If not, retire it.
- Is it stable, blocking nothing and carrying acceptable risk? Retain it with a review date.
- Is the main constraint hardware, capacity or hosting cost? Rehost or relocate, as a temporary step if the code also needs work.
Change the runtime, product, integrations or core
Continue with these questions:
- Does the code work while the runtime can't be updated? Replatform.
- Would a standard product cover this process well enough? Repurchase.
- Does the core work but fail to connect to other systems? Encapsulate first.
- Does the structure slow releases or block scaling? Refactor, usually one piece at a time.
- Can the core not support the features you need, with fixes costing more than a rewrite? Rebuild.
When a system needs deep change, start with the business logic before the UI or the database. Once the logic sits in clear modules, you can replace the interface and the data store behind it, while a new interface built first tends to lock the old logic in place.
Dmytro Dobrytskyi, CEO at Mind Studios, explains why one answer for the whole platform is usually the wrong modernization strategy:
Most founders come to us asking whether to rebuild the platform, as if it were one decision. It rarely is. On the DJ platform we've supported since 2013, the product was rebuilt and the infrastructure moved to AWS, two separate calls made at different points. Treat each system as its own decision and fund the one that's actually holding revenue back.
If scoring turns into an architecture debate, an architecture advisory review can clarify the trade-offs before the team commits to a target design.
Rebuild or fix: what our legacy software modernization projects show
A rebuild pays off when the core can't support what the business needs and fixing it would take more time and money than writing it again. Our two projects show different sides of that test: on the MP3Pool platform, users were leaving over problems in the core, while the review of the Envol app favored a rebuild on both time and cost.
MP3Pool: outdated at the core
Work on MP3Pool started with falling traffic that was cutting into income while competitors pulled ahead on features and usability. The team surveyed users directly and found five reasons they were leaving:
- inconvenient search
- no bulk downloads
- errors in MP3 ID tags
- slow performance
- a dated look
A redesign alone wouldn't have fixed search, downloads or tags, so the team concluded the site was outdated at the core and built a new solution. It has a Vue.js single-page app with server-side rendering on Nuxt, a Ruby on Rails backend, FFmpeg preparing tracks for HLS streaming and a validation system for uploaded MP3 tags.
The new site went live on a new server, and a dedicated API synced user data between the servers, so active subscriptions and personal data carried over. Then the main domain was pointed to the new server, and the old site moved to a subdomain hidden from search indexing.
For subscribers, the move looked like a regular interface update.
Envol: rebuilding was the cheaper path
Envol is a wellness product for people recovering from chronic illness and injury. Its existing Android app struggled with the main thing users came for: guided audio. Large files caused frequent interruptions and long loading times, and the audio library was expected to keep growing.
After reviewing the app, the team concluded it made more sense, in both time and money, to build a new app from scratch and move existing users to it, with an iOS app built at the same time.
The new architecture prepares streams at several quality levels: high-quality originals go to AWS S3, an AWS Lambda script splits them, and each user gets the stream that matches their connection.
Existing users moved over without registering again: all data except passwords was migrated, including subscription statuses, and tracking stats were matched to each user without loss.
What to compare before you decide
Envol's comparison of time and money only holds if you price both options over the same planning horizon. For the fix and the rebuild, add up:
- the changes, including work the fix will need again later
- testing, including behavior nobody documented
- moving users, subscriptions and data
- running old and new in parallel until cutover
- support for the rest of the horizon
A fix can look cheaper on the first line and lose on the last.
Mind Studios' insight: Sorting the problems users and your team report into surface and core is a quick first test. If most come from core behavior, a redesign leaves the underlying constraints in place.
If your team is split on fixing or rebuilding the core, the deciding question is which option costs less over the same planning horizon.
A phased legacy system modernization roadmap
A safe legacy system modernization runs in five phases, from assessment to retiring the old system. Old and new run in parallel through the middle phases, and the switch happens only against agreed criteria with a way back. Work continues after cutover.
- Assess and map dependencies: systems, integrations, data flows and their users, including hidden users of a "dead" system.
- Pilot: run the full cycle, rollback test included, on one low-impact component.
- Migrate in stages with parallel running: move one piece at a time while the old system serves production, and compare outputs.
- Switch over against criteria, with a rollback ready.
- Retire, hand over and keep improving: shut down the old system once the receiving team can run the new one, document what changed and plan next steps.
Cutover criteria and a rollback path
Agree on the cutover checklist before migration starts so nobody negotiates it under pressure:
- Data reconciliation: record counts and key totals match between old and new.
- Behavior: critical user flows pass on the new system with production data.
- Performance: response times match or beat the old system under real load.
- Rollback: the way back is rehearsed, and everyone knows who triggers it.
- Support: the on-call team knows the new system and its alerts.
For each migrated function, the plan should also name which system owns writes before and after the switch, so orders or subscriptions are never accepted in two places at once. If rollback stays available, the rehearsal should confirm that changes made after cutover return to the old system without missing or duplicated records.
On the DJ platform's move to AWS, the team set up a new AWS environment, upgraded Node.js and long-outdated packages, rebuilt the FFmpeg-based audio worker and tested each supplier ingestion route separately.
During parallel running, new content went straight to S3 while Rails kept processing on the old hardware. At cutover, the old production environment stayed live for one month as a fallback, was never needed and was then shut down. The migration ran with zero downtime.
Mind Studios' recommendation: Decide in advance when the legacy data structures and sync processes get removed, because that is your point of no return. Microsoft's architecture guidance notes that rollback stays possible while they exist, and after removal going back means restoring them and replaying data changes.
Production data passes between environments in a move like this, so the partner's processes matter as much as the plan. As listed on our modernization service page, Mind Studios is ISO 27001 and ISO 9001 certified.
The work didn't stop at cutover. The team added CloudFront as a CDN, which cut delivery costs by 30%, and blocked scripts pulling 100–500 tracks per minute at the edge before they reached the application. Neither task was in the original scope.
Phase 5 ends when the team that will run the system can deploy, monitor and restore it without the people who built it. That handover covers runbooks, access to every environment and account, and a named owner for support and incidents.
Strangler fig pattern: replace the system piece by piece
For a large system, the strangler fig approach is a standard way to run phase 3. A facade sits in front of the legacy system and sends each request either to the old code or to a new service. As more features move over, more traffic goes to the new side, until the old system can be switched off.
Microsoft's guidance says the pattern fits when requests to the old system can be intercepted and the old system can keep running for a while. It fits poorly when you can't put anything in front of the legacy system, when it's small enough to replace in one go or when it has to be shut down quickly.
The cost is a temporary architecture: two systems with a layer between them that must not become a single point of failure or a bottleneck, plus data stores both sides use at once. Budget for the facade, and make its removal a step in the project plan.
Where AI helps in a modernization project, and where it doesn't
AI tools are useful early, when the team needs to understand code nobody fully remembers. In a GitHub engineering walkthrough from January 2025, an engineer uses an AI assistant to explain a legacy COBOL application, draw a sequence diagram of how it works and generate tests before changing code, while stressing that every output needs human review.
Treat that output as a draft an engineer checks against the running system. A generated summary can miss what the business needs the code to do, and a dependency map can miss calls made through configuration files or database triggers.
Generated tests need the same check, since a test derived from the code also locks in its bugs. Have those tests reviewed and in place before AI-assisted changes begin.
In Google's 2025 DORA report, 30% of respondents reported little or no trust in AI-generated code, and AI adoption still had a negative relationship with delivery stability, which the authors tie to weak controls such as automated testing that a legacy codebase often lacks.
Risks that stall modernization and how to contain them
Five risks can stall a legacy modernization project: data that doesn't survive the move, knowledge that left with former team members, downtime the business can't absorb, scope that keeps growing and people who don't adopt the new system. Each is easier to contain before migration than after it.
- Data loss or corruption: old data rarely matches its documentation, so run trial migrations on a copy of production and map every field.
- Lost knowledge: when the builders are gone, behavior lives only in the code. Document critical flows, write tests around them and keep someone from the current team on the project.
- Downtime: agree on two targets per system. The recovery point objective (RPO) is how much data, measured in time, you can afford to lose, and the recovery time objective (RTO) is how long the system can be down. Together they decide between parallel running and a maintenance window.
- Scope creep: agree on the critical workflows each phase must preserve, decide explicitly which legacy features can be retired and give someone on the business side the authority to say "after the switch."
- People: keep familiar flows where you can, announce changes before they ship and train the support team before cutover.
What drives modernization cost and timeline
Cost and timeline depend on five things: how large and interconnected the system is, the approach you choose, the volume and condition of the data, how much downtime the business can accept and the regulations it operates under. Two more costs are easy to miss: running two systems in parallel, and the cost of waiting.
| Factor | Why it moves cost | How to lower it |
|---|---|---|
| Size and coupling | More integrations to test and reroute | Map dependencies; move loosely coupled parts first |
| Approach | Code changes and regression testing expand scope | Match the depth of change to each system's problem |
| Data volume and quality | Cleanup takes longer than the transfer | Clean and archive before migrating |
| Downtime tolerance | Zero downtime requires parallel running and sync | Agree on RPO and RTO for each system |
| Regulation | Audits, residency rules and sign-offs add steps | Bring compliance into the assessment |
| Documentation | Unknown behavior has to be rediscovered | Document flows and write tests early |
Parallel running is easy to leave out of a legacy modernization budget. During the transition you pay for two environments, two sets of monitoring and the sync between them, and that overlap is what keeps a rollback possible.
The cost of waiting is harder to see because it never arrives as an invoice. A stack that can't be updated means features that don't ship and patches that can't be applied. The same GAO report shows how slowly this moves: of the 10 critical federal systems GAO first flagged in 2019, agencies had finished modernizing only three by February 2025.
Where to start with legacy system modernization
Start by assessing every system you run, then pilot a contained piece of the most urgent one. You come out with a dependency map, a provisional R for each system and evidence from production before you commit budget to the bigger phases.
The first system to assess is the one where failure risk, blocked revenue or the cost of delay makes waiting hardest to justify, and that is often a different system from the oldest one.
If you're also choosing who should run the project, ask how a team assesses systems, runs parallel periods and decides when to switch over before you look at its stack list. Our overview of legacy modernization partners covers what else to compare.
If you need a starting scope for your own platform, a modernization session with our team can help identify the first system to assess and the recovery requirements to settle before migration.
FAQ
What is legacy system modernization?
It's the process of updating a system your business still depends on so it can keep supporting growth. That can mean new hosting, a new runtime, a new architecture or a full rewrite. Most companies modernize in phases and keep the old system serving customers until the new one has proven itself under real traffic.
How do you modernize a legacy system without downtime?
Run the old and new systems in parallel and move traffic over in stages. Keep data synced, decide which system owns writes, compare outputs and switch only when agreed criteria are met. Keep the old environment as a fallback until the new one has handled real traffic. If brief downtime is acceptable, a planned maintenance window can be simpler.
What are the 7 Rs of legacy modernization?
The AWS set of seven migration strategies:
- Retire: shut the system down
- Retain: keep it as is for now
- Rehost: move it to new hosting unchanged
- Relocate: move the whole platform to its cloud version
- Repurchase: replace it with an off-the-shelf product
- Replatform: move it with light optimization
- Refactor or re-architect: change its structure
Encapsulation and rebuild are not part of this set.
What is application modernization, and how is it different from legacy system modernization?
It updates a single application: its code, architecture, frameworks and dependencies. Legacy system modernization goes further. It also covers the infrastructure the application runs on, its data stores, the integrations around it and the processes people run on top, so one system project often includes several application projects.
How long does legacy system modernization take?
The timeline depends on five factors:
- how many systems and integrations are in scope
- how tightly they're connected
- the volume and quality of the data
- downtime tolerance, which sets how long parallel running lasts
- the approach (rehosting moves faster than refactoring or a rebuild)
An assessment phase gives you a timeline you can plan around.
Should you rebuild or refactor a legacy application?
Refactor when the problems sit in a few modules, the data model still fits and the team can test changes safely. Rebuild when the core can't support features the business needs and fixing it would cost more over the same horizon than rewriting. Either way, plan how users and their data will move before you commit.
Why do legacy modernization projects fail?
Common causes include:
- one approach forced onto every system
- dependencies discovered in the middle of migration
- scope that grows into a rewrite nobody approved
- data not reconciled before cutover
- no tested way to roll back
- knowledge that left with the original team
Is enterprise application modernization different for a mid-size company?
The methods are the same, but the constraints differ. Enterprise programs usually cover large portfolios with dedicated migration teams. A mid-size company has fewer systems and less room for error: one platform often brings in most of the revenue, the team is busy shipping features and downtime hits customers directly. That makes phasing and rollback planning more important.